Free renewal in one year
To meet the demands of customers, our Associate-Developer-Apache-Spark-3.5 exam preparatory files offer free renewal in one year, which might sound incredible but, as a matter of fact, is a truth. As you know, the majority of people are curious about new things, especially things that they have never heard about before. As a result, aperiodic renewal can attract more people to pay attention to our Databricks Associate-Developer-Apache-Spark-3.5 test prep. Of course, our Associate-Developer-Apache-Spark-3.5 study materials, with serving the people as the paramount goal, provide customers whoever make a purchase for our exam files with free renewal for one year mainly in order to make up for what the customers have neglected in the study materials. What's more, our Associate-Developer-Apache-Spark-3.5 exam preparatory files carry out a series of discounts a feedback our customers. In this way, choosing our Associate-Developer-Apache-Spark-3.5 test prep is able to bring you more benefits than that of all other exam files.
This is the era of information technology where all kinds of information is flooded on the Internet (Associate-Developer-Apache-Spark-3.5 study materials), making it much more difficult for those who prepare for the tests to get comprehensive understanding about the exam files they are going to choose. However, there is still one kind of Associate-Developer-Apache-Spark-3.5 exam preparatory that is one hundred percent trustworthy for the general public to testify their quality that is our Associate-Developer-Apache-Spark-3.5 test prep files. The reason why I claim our Associate-Developer-Apache-Spark-3.5 study materials with assurance is due to the following aspects.

Enough for the tests after 20 or 30 hours'practice
It is a sort of great magic for those who have bought our Associate-Developer-Apache-Spark-3.5 study materials as many of them can take part in the exam just after 20 or 30 hours'practice. They are quite surprised by the great progress they have made in such a short period. Is it a kind of power granted by God? No, certainly not. The true reason for the speedy improvement is that our Associate-Developer-Apache-Spark-3.5 exam preparatory files are so ingeniously organized that they are suitable for everybody, no matter what kind of degree he or she is in concerning their knowledge of the targeted exams. Therefore, once they have used our Databricks Associate-Developer-Apache-Spark-3.5 test prep materials, they can easily get the hang of the key tested point so that they are more likely get better grades than those without the help coming from our Associate-Developer-Apache-Spark-3.5 study materials.
High guarantee for the personal interests of customers
Our Databricks Associate-Developer-Apache-Spark-3.5 exam preparatory files guarantee personal interests of customers concerning the following two aspects. On the one hand, the payment of our exam files is supported by the authoritative payment platform in the world, which protects the personal information of our customers from leaking out (Associate-Developer-Apache-Spark-3.5 test prep materials). On the other hand, customers who have failed in the exam luckily can ask for full refund or changing other exam files for free. Of course, this kind of situation can be rarely seen as few people will not be able to pass the exams under the guidance of our Associate-Developer-Apache-Spark-3.5 study materials.
After purchase, Instant Download: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Using Pandas API on Spark | 5% | - Pandas API
|
| Developing Apache Spark DataFrame API Applications | 30% | - DataFrame Operations
|
| Using Spark SQL | 20% | - Spark SQL Operations
|
| Using Spark Connect to Deploy Applications | 5% | - Spark Connect
|
| Troubleshooting and Tuning | 10% | - Performance Optimization
|
| Apache Spark Architecture and Components | 20% | - Spark Architecture
|
| Structured Streaming | 10% | - Streaming Applications
|
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
12 of 55.
A data scientist has been investigating user profile data to build features for their model. After some exploratory data analysis, the data scientist identified that some records in the user profiles contain NULL values in too many fields to be useful.
The schema of the user profile table looks like this:
user_id STRING,
username STRING,
date_of_birth DATE,
country STRING,
created_at TIMESTAMP
The data scientist decided that if any record contains a NULL value in any field, they want to remove that record from the output before further processing.
Which block of Spark code can be used to achieve these requirements?
- A. filtered_users = raw_users.dropna(how="any")
- B. filtered_users = raw_users.dropna(how="all")
- C. filtered_users = raw_users.na.drop("all")
- D. filtered_users = raw_users.na.drop("any")
Correct Answer: A 🗳️
Explanation: Only visible for Dumpexams members. You can sign-up / login (it's free).
How can a Spark developer ensure optimal resource utilization when running Spark jobs in Local Mode for testing?
Options:
- A. Use the spark.dynamicAllocation.enabled property to scale resources dynamically.
- B. Increase the number of local threads based on the number of CPU cores.
- C. Set the spark.executor.memory property to a large value.
- D. Configure the application to run in cluster mode instead of local mode.
Correct Answer: B 🗳️
Explanation: Only visible for Dumpexams members. You can sign-up / login (it's free).
16 of 55.
A data engineer is reviewing a Spark application that applies several transformations to a DataFrame but notices that the job does not start executing immediately.
Which two characteristics of Apache Spark's execution model explain this behavior? (Choose 2 answers)
- A. Only actions trigger the execution of the transformation pipeline.
- B. The Spark engine optimizes the execution plan during the transformations, causing delays.
- C. Transformations are executed immediately to build the lineage graph.
- D. Transformations are evaluated lazily.
- E. The Spark engine requires manual intervention to start executing transformations.
Correct Answer: A,D 🗳️
Explanation: Only visible for Dumpexams members. You can sign-up / login (it's free).
A data engineer is asked to build an ingestion pipeline for a set of Parquet files delivered by an upstream team on a nightly basis. The data is stored in a directory structure with a base path of "/path/events/data". The upstream team drops daily data into the underlying subdirectories following the convention year/month/day.
A few examples of the directory structure are: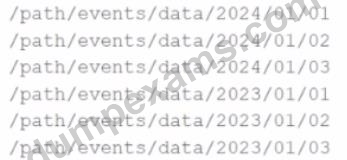
Which of the following code snippets will read all the data within the directory structure?
- A. df = spark.read.option("recursiveFileLookup", "true").parquet("/path/events/data/")
- B. df = spark.read.option("inferSchema", "true").parquet("/path/events/data/")
- C. df = spark.read.parquet("/path/events/data/*")
- D. df = spark.read.parquet("/path/events/data/")
Correct Answer: A 🗳️
Explanation: Only visible for Dumpexams members. You can sign-up / login (it's free).
A data engineer writes the following code to join two DataFrames df1 and df2:
df1 = spark.read.csv("sales_data.csv") # ~10 GB
df2 = spark.read.csv("product_data.csv") # ~8 MB
result = df1.join(df2, df1.product_id == df2.product_id)
Which join strategy will Spark use?
- A. Shuffle join, as the size difference between df1 and df2 is too large for a broadcast join to work efficiently
- B. Broadcast join, as df2 is smaller than the default broadcast threshold
- C. Shuffle join because no broadcast hints were provided
- D. Shuffle join, because AQE is not enabled, and Spark uses a static query plan
Correct Answer: B 🗳️
Explanation: Only visible for Dumpexams members. You can sign-up / login (it's free).